Input images up to 1280 x 720 (width x height). Larger images are rejected with HTTP 413, not downscaled — resize first.
Parameters
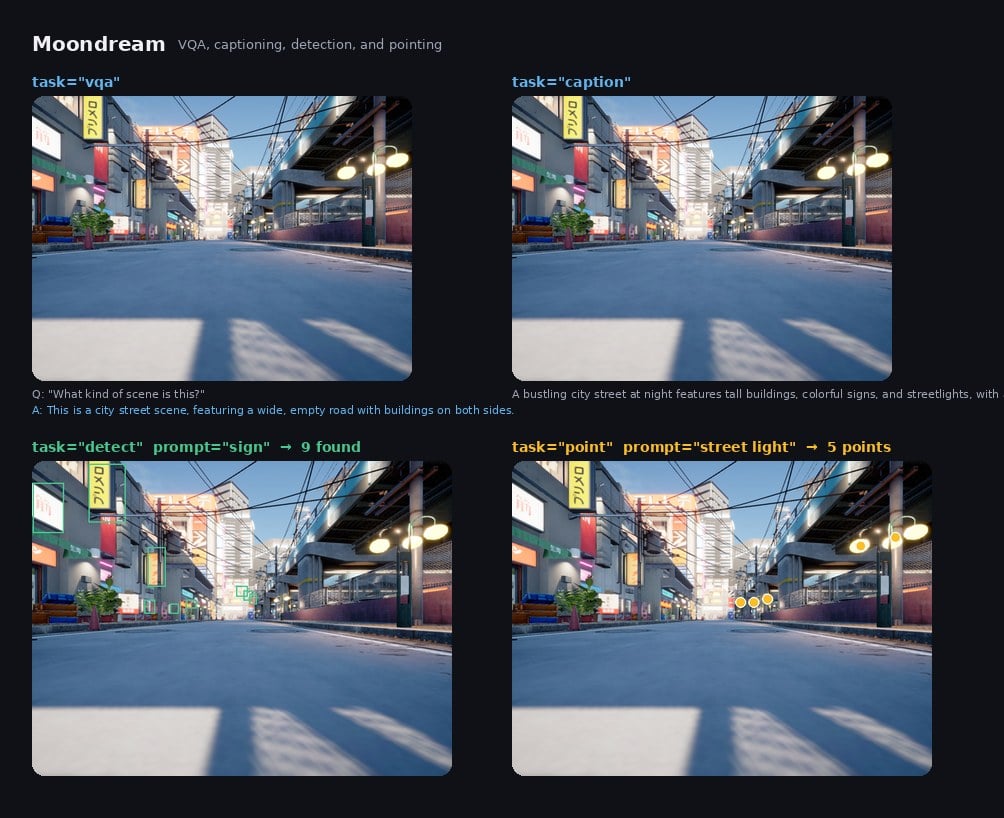
Task type - “vqa” (Visual Question Answering), “caption” (Image Captioning), “detect” (Object Detection), or “point” (Pointing/Clickable points).
Returns
Dict[str, Any]: Backend JSON response containing generated text or structured data.- For vqa/caption: {“output”: “text response”}
- For detect: {“output”: {“boxes”: […], “scores”: […], “labels”: […]}}
- For point: {“output”: numpy array of (x,y) points}
Example
Example Output